Research concept · This article describes a proposed system and evaluation program. No measured SimW1 benchmark results or validated capabilities are presented.
01 / The ambition
The future is not a document. It is a system in motion.
A decision rarely ends where it begins. A new product changes what customers consider. Their choices change demand. Demand changes inventory, staffing, and delivery. Those constraints change the experience of the next customer. What first looked like one decision becomes a chain of interactions.
Yet much of the work that precedes a decision still happens in static documents: a forecast, a presentation, a list of assumptions, a recommendation. These are valuable tools. But the relationships between them are often left implicit, and the consequences of changing an assumption are difficult to inspect.
SimW1 is OpenX’s proposed simulation world model. Our ambition is to give teams a structured place to rehearse choices: describe the relevant world, identify what can change, and explore how different paths might unfold under explicit assumptions.
The aim is not to replace judgment with a single answer. It is to make judgment better informed. A useful simulation should reveal where a decision is robust, where it is fragile, and which missing piece of evidence would most change what we choose.
Not a claim to know the future. A way to ask better questions of it.
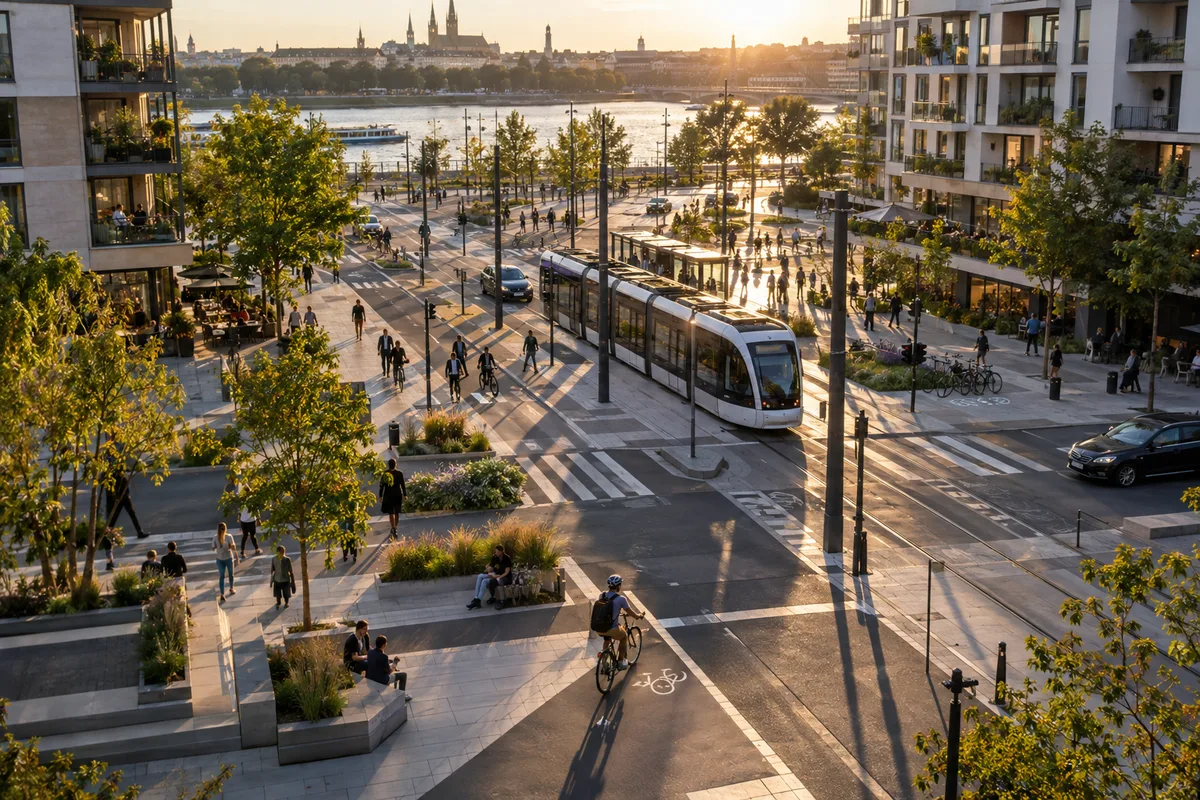
ActorsResourcesConstraintsEnvironment
From a scene to a bounded model. A visual environment alone does not define the rules, evidence, or causal mechanisms. Labels show conceptual model layers—not detected entities or a live digital twin.
02 / What we mean by a world model
A world small enough to inspect. Rich enough to matter.
In this proposal, a “world” is a bounded representation of a decision environment—not a complete replica of reality. It contains a starting state, actors, available actions, resources, constraints, and rules for how those elements might change together over time.
A retail world might contain stores, customers, inventory, delivery schedules, and a pricing policy. A logistics world might contain facilities, routes, orders, vehicle capacity, and disruption scenarios. The boundary matters: anything left outside the model can still affect the real outcome.
The intended input is a question supported by evidence. The intended output is a set of conditional trajectories, comparisons, and uncertainty estimates, accompanied by the assumptions that produced them. A narrative can help explain a trajectory, but should not substitute for a traceable state or a measurable outcome.
We distinguish four layers: observations that came from evidence; assumptions introduced to fill gaps; mechanisms used to connect states and actions; and outcomes generated by a run. Keeping these layers separate is a design objective, not a claim that all such controls have already been implemented.
This article does not disclose a trained architecture, parameter count, training corpus, or verified model release. The workflow below describes the system we intend to evaluate. It should not be read as a specification of demonstrated capabilities.
Evidence is not the same as a convincing explanation.
Consider two scenarios that produce the same sales curve. In one, demand grows because more people hear about the product. In the other, the same growth comes from a price change. The curves may look identical today, but a different intervention could make them diverge tomorrow. An explanation is useful only if it clarifies what evidence would distinguish these accounts.
The proposed world representation therefore needs more than a description of a setting. It needs an explicit relationship between observations and assumptions. A delivery time from an operational record, an estimated response from a survey, and a hypothetical response introduced by an analyst should not arrive at the same evidentiary status.
We want a decision team to be able to trace a result backward: from an outcome to a sequence of events, from those events to a mechanism, and from that mechanism to the evidence or assumption supporting it. Where that chain breaks, the gap should become a research question rather than disappear into fluent language.
03 / A worked example
Launch now. Pilot first. Or wait for better evidence.
Imagine a team considering a new product. Its question is not simply “Will people like it?” The practical question is whether a launch can create durable demand without exceeding fulfillment capacity or committing too much capital before the team has learned enough.
We would begin by defining what is known: historical demand, existing capacity, estimated unit costs, and the evidence behind customer assumptions. Unknowns remain visible. An assumed adoption rate should not quietly become an observed fact because it appears inside a simulation.
ONE STARTING WORLDTHREE POSSIBLE INTERVENTIONS
Shared baselineLaunch broadly
Demand exposure
Capacity pressure
Larger commitment
A larger intervention reaches more of the network at once. Inspect whether fulfillment, cash, and service constraints remain feasible.
Interactive explanation of a proposed workflow. Selecting a path changes this diagram; it does not run SimW1 or produce a forecast.
Path A
Launch broadly
Explore demand and operational pressure under a larger initial commitment.
Path B
Run a pilot
Trade early reach for a chance to learn before expanding.
Path C
Wait and investigate
Compare the cost of delay with the value of resolving uncertainty.
All three paths should start from the same baseline. Where appropriate, paired random seeds would expose them to comparable external conditions. The intervention changes; unrelated starting assumptions do not change merely to make one option look better.
The comparison would examine more than revenue: stockouts, cash requirements, service delays, and sensitivity to customer response. Repeated runs would reveal whether a preferred path depends on a narrow set of favorable conditions. They would not turn an uncertain model into a guarantee.
Finally, the pilot or launch would create observations. Those observations could challenge the assumptions and guide a subsequent evaluation. This example illustrates the proposed workflow; it is not a customer case study or a measured SimW1 result.
OPENX / POSSIBLE WORLDS
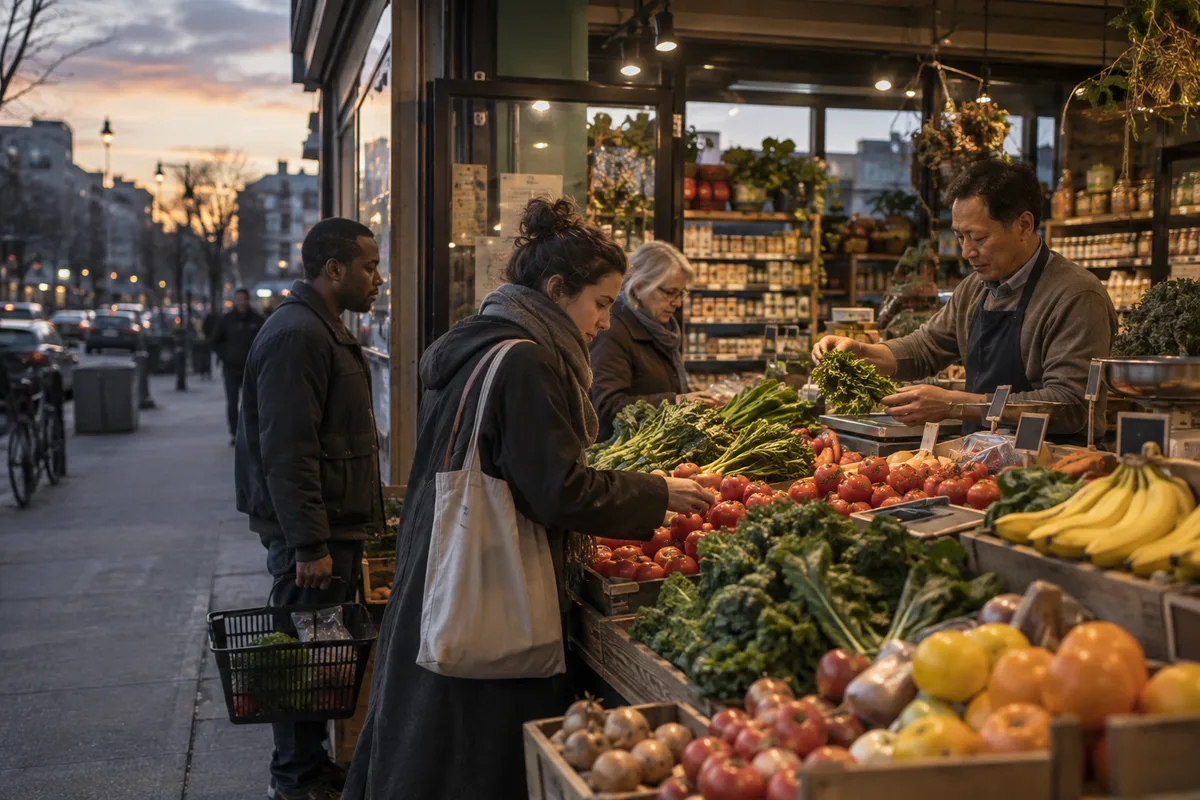
A different choice at every shelf.
What changes if we launch in a smaller market first?
AI-generated concept illustration · Not a deployment photograph. A proposed retail world connects customer response with inventory, pricing, and replenishment. The illustration depicts a setting—not observed customer behavior.
Rehearsal is a way to choose the next experiment.
A model does not have to resolve every uncertainty to be useful. It may reveal that two decisions perform similarly across most plausible conditions, or that one missing quantity dominates the comparison. In those cases, the next action might be to collect evidence rather than commit to the favored scenario.
For the product example, the team might discover that uncertainty about repeat purchasing matters more than uncertainty about initial interest. A short launch survey would then answer the wrong question. A pilot designed to observe repeat behavior could be more informative, provided its participants and conditions are relevant to the wider market.
This connects simulation to experiment design. Before collecting more data, ask which observation could change the choice. After collecting it, ask whether the new evidence supports the assumed mechanism. The simulation should help organize that conversation, not automatically settle it.
04 / The learning loop
From evidence to alternatives. From alternatives back to evidence.
01Ground — document evidence, uncertainty, and the decision boundary.
02Build — represent actors, resources, mechanisms, and constraints.
03Fork — change an intervention while holding the baseline comparable.
04Simulate — examine repeated conditional paths and failure cases.
05Validate — compare predictions with observations and revise.
The important feature of this loop is its return to evidence. Without that return, an increasingly detailed simulation can become an increasingly elaborate expression of its initial assumptions. More agents and more time steps do not, by themselves, establish validity.
We want users to be able to ask why a result changed, which assumptions dominate it, and whether an alternative explanation is equally consistent with the available data. These are evaluation goals that should shape the product from the beginning.
A model can predict an event and still recommend a poor action. It can comply with a budget while misrepresenting people. It can match an average while missing the tail of the distribution that matters most. For that reason, we propose twelve distinct evaluation tracks.
The first three use established external benchmarks. The fourth proposes an evaluation using an external behavioral dataset. The remaining eight are OpenX protocol proposals, not public benchmark suites or completed experiments. Each requires a frozen test design, appropriate data access, and an executable evaluation before a result can be reported.
All twelve are currently marked Evaluation planned. Each track sets out a question, a test design, and an interpretation boundary. Measured results will require completed evaluations and supporting artifacts.
01 / PredictionEvaluation planned
Event forecasting
Can a probability about the future stand up to the future itself?
ForecastBench · external benchmark
Swipe to explore the full chart
Lines and distinct markers illustrate performance across different evaluation conditions. The values and named comparison models are fictional placeholders for this design—not measured results. See the test design below for the actual proposed evaluation.
Test design
Record forecasts before events resolve, with a fixed information cutoff. Evaluate on resolved questions using the benchmark’s published protocol. Keep tool-assisted and unassisted configurations separate.
What we would measure
Official ForecastBench scoring; uncertainty intervals and question counts.
What it would not prove
Forecasting association does not establish the effect of an intervention. Unresolved questions cannot be counted as successes.
Does the model track changes in quantities, not just tell a plausible story?
GIFT-Eval · external benchmark
Swipe to explore the full chart
Lines and distinct markers illustrate performance across different evaluation conditions. The values and named comparison models are fictional placeholders for this design—not measured results. See the test design below for the actual proposed evaluation.
Test design
Use the published dataset splits and forecasting protocol. Report performance by dataset, forecast length, and frequency, with historical information separated from future observations.
What we would measure
Official point and probabilistic forecast metrics; error by horizon.
What it would not prove
A strong average can hide poor performance on a particular industry. Forecasting an existing series does not validate a new policy.
Can the model distinguish seeing a pattern from changing its cause?
CLadder · external benchmark
Swipe to explore the full chart
Lines and distinct markers illustrate performance across different evaluation conditions. The values and named comparison models are fictional placeholders for this design—not measured results. See the test design below for the actual proposed evaluation.
Test design
Evaluate the formal causal questions under their supplied assumptions and graphs. Separate observational, interventional, and counterfactual questions instead of reporting one opaque total.
What we would measure
Answer accuracy by causal task, with uncertainty intervals.
What it would not prove
Success on formal problems does not prove that a causal graph inferred from a real organization is correct.
Do simulated choices resemble observed choices on unfamiliar tasks?
Psych-101 · proposed evaluation using an external dataset
Swipe to explore the full chart
Lines and distinct markers illustrate performance across different evaluation conditions. The values and named comparison models are fictional placeholders for this design—not measured results. See the test design below for the actual proposed evaluation.
Test design
Design participant- and experiment-held-out tests, subject to dataset access and licensing. Keep repeated choices from the same person together when splitting and estimating uncertainty.
What we would measure
Choice negative log-likelihood; task-level and held-out-experiment breakdowns.
What it would not prove
Experimental participants are not a representative sample of every population. This would not validate individual profiling or population-wide claims.
When the true effect is known, can the model recover it?
OpenX proposed protocol
Swipe to explore the full chart
Lines and distinct markers illustrate performance across different evaluation conditions. The values and named comparison models are fictional placeholders for this design—not measured results. See the test design below for the actual proposed evaluation.
Test design
Generate controlled structural causal systems with known interventions. Hold out system structures and compare estimated effects with the generator’s ground truth across confounding and noise conditions.
What we would measure
Effect estimation error, sign accuracy, and interval coverage.
What it would not prove
Synthetic ground truth tests reasoning within the generator’s assumptions; it is not proof of real-world causal identification.
06 / DecisionsEvaluation planned
Decision quality
Does using the model lead to a better choice under a defined objective?
OpenX proposed protocol · informed by predict-then-optimize evaluation
Swipe to explore the full chart
Lines and distinct markers illustrate performance across different evaluation conditions. The values and named comparison models are fictional placeholders for this design—not measured results. See the test design below for the actual proposed evaluation.
Test design
Freeze objectives and feasible actions before scoring. Evaluate routing, inventory, or allocation choices in held-out problems with known outcomes or a computable oracle. Compare with simple policies and specialist solvers.
What we would measure
Decision regret and objective value; report infeasible decisions separately.
What it would not prove
An oracle for a bounded optimization problem is not an oracle for society. The chosen objective may omit important consequences.
Does a recommended plan remain possible when constraints become binding?
OpenX proposed protocol
Swipe to explore the full chart
Columns illustrate how a model comparison could be presented. The values and named comparison models are fictional placeholders for this design—not measured results. See the test design below for the actual proposed evaluation.
Test design
Define capacity, inventory, timing, and budget requirements as machine-checkable conditions. Test combinations of tight constraints and infeasible requests, including whether the system identifies when no valid plan exists.
What we would measure
Violation frequency, violation severity, and infeasibility detection.
What it would not prove
Passing formal checks only covers encoded constraints. Unwritten operating requirements can still invalidate a plan.
08 / ReliabilityEvaluation planned
Long-horizon stability
How quickly do small errors grow into a different world?
OpenX proposed protocol
Swipe to explore the full chart
Lines and distinct markers illustrate performance across different evaluation conditions. The values and named comparison models are fictional placeholders for this design—not measured results. See the test design below for the actual proposed evaluation.
Test design
Compare rollouts with reference trajectories over progressively longer horizons. Separate open-loop prediction from runs that receive new observations. Check conservation and bookkeeping invariants at each step.
What we would measure
State error by rollout length and invariant violations over time.
What it would not prove
A stable trajectory can still be consistently wrong. Horizon must be reported in domain-relevant units, not only simulation steps.
09 / ReliabilityEvaluation planned
Uncertainty calibration
When the model says an outcome is likely, how often does it happen?
OpenX proposed protocol
Swipe to explore the full chart
Lines and distinct markers illustrate performance across different evaluation conditions. The values and named comparison models are fictional placeholders for this design—not measured results. See the test design below for the actual proposed evaluation.
Test design
Evaluate probabilities and predictive intervals against held-out observations. Use reliability plots alongside proper scoring rules; report sample counts and uncertainty for each probability bin.
What we would measure
Brier or log score for events; interval coverage and width for quantities.
What it would not prove
Wide intervals can achieve coverage without being useful. Calibration must be checked alongside sharpness and against domain shift.
10 / ReliabilityEvaluation planned
Shock robustness
What happens when the operating conditions stop resembling the past?
OpenX proposed protocol
Swipe to explore the full chart
Lines and distinct markers illustrate performance across different evaluation conditions. The values and named comparison models are fictional placeholders for this design—not measured results. See the test design below for the actual proposed evaluation.
Test design
Reserve disruption families and severities for testing: supply delays, demand spikes, outages, or missing observations. Compare the same policy and forecast tasks before and after each change.
What we would measure
Performance degradation versus shock severity; constraint failures.
What it would not prove
Designed stress tests cannot enumerate every surprise. Passing familiar shocks does not establish resilience to unknown ones.
11 / Behavior & causalityEvaluation planned
Population-response fidelity
Does the simulation preserve disagreement and variation, not just an average?
OpenX proposed protocol
Swipe to explore the full chart
Columns illustrate how a model comparison could be presented. The values and named comparison models are fictional placeholders for this design—not measured results. See the test design below for the actual proposed evaluation.
Test design
Use appropriately consented or licensed aggregate response data. Compare held-out distributions across contexts and sufficiently sized groups. Measure rare responses as well as common ones, while protecting privacy.
What we would measure
Distribution distance, aggregate response error, and subgroup gaps.
What it would not prove
Matching aggregate data does not mean the model represents a particular person. Small groups may be too uncertain to report safely.
12 / ReliabilityEvaluation planned
Cross-domain generalization
Does a useful model stay useful outside the setting where it was tuned?
OpenX proposed protocol
Swipe to explore the full chart
Columns illustrate how a model comparison could be presented. The values and named comparison models are fictional placeholders for this design—not measured results. See the test design below for the actual proposed evaluation.
Test design
Hold out entire domains, locations, or operating regimes. Publish a transfer matrix and clearly distinguish zero-shot evaluation from adaptation with new domain data.
What we would measure
Task-appropriate performance by domain; degradation relative to in-domain tests.
What it would not prove
There is no meaningful single percentage across incompatible tasks. Domain-specific evidence remains necessary before deployment.
Comparisons that compare the same thing.
A useful result needs context. We would compare against simple historical or rule-based baselines, appropriate specialist methods, and general-purpose models where the input and output formats are compatible. Internal ablations would remove actually implemented components to measure their contribution.
Each comparison must state the dataset version, split, information cutoff, tools, model version, compute budget, and scoring rule. Tool-assisted systems should not silently compete with systems denied the same evidence. Missing outputs and failed runs should not disappear from the denominator.
For repeated or correlated observations, uncertainty estimates should respect the unit of independence: a participant, a series, a scenario, or an event. We would publish sample counts and uncertainty intervals, plus important failure cases, rather than rely on point estimates alone.
No comparative result against GPT‑6 Astra or another commercial model is available in this announcement. A score copied from an unrelated leaderboard would not be a valid SimW1 comparison. Any future head-to-head claim would require a matched protocol and actual runs.
When results exist, their charts should suit their meaning: forecast error by horizon, calibration curves, intervention-effect plots, decision regret, and cross-domain heatmaps. Combining all of these into one “world intelligence” percentage would obscure the differences the tests are designed to reveal.
06 / Questions worth exploring
Different industries. Different evidence.
We see potential in domains where a choice can be bounded, assumptions can be documented, and outcomes can eventually be observed. These examples are proposed applications, not claims of deployment or validation.
Retail and product strategy
Compare rollout strategies, inventory policies, and customer-response assumptions. Useful evaluation would examine held-out demand, service levels, stockouts, and the cost of choosing the wrong plan—not just whether a simulated customer gives a convincing explanation.
Logistics and manufacturing
Explore a facility delay, a route change, or a different production schedule. Capacity and material constraints provide concrete checks. A simulated gain is only meaningful if the plan remains feasible and the operational assumptions survive comparison with observed data.
Energy and infrastructure
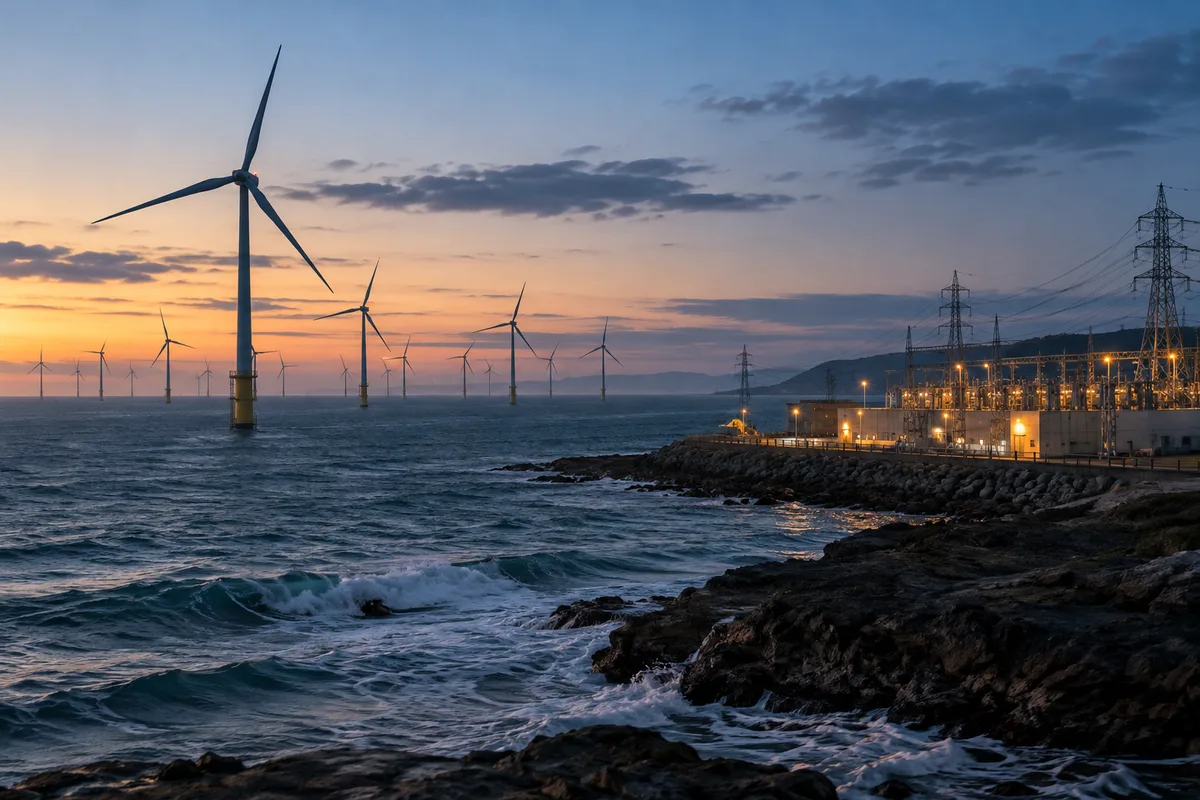
Investigate planning scenarios under uncertain loads, resource availability, or maintenance schedules. These domains require specialist physical models and engineering review. A general simulation interface should not be mistaken for certified operational control.
OPENX / POSSIBLE WORLDS
A connected system. A changing balance.
How do maintenance schedules interact with uncertain load?
AI-generated concept illustration · Not a deployment photograph. Energy planning scenarios would need domain-specific physical models and engineering review. SimW1’s concept is decision rehearsal, not autonomous grid operation.
Capital allocation
Rehearse how a bounded budget could be distributed across initiatives under different demand and cost assumptions. The useful question is how sensitive the decision is to those assumptions. This is not a promise to predict asset prices or deliver investment returns.
Organizations and public services
Explore scheduling, resource allocation, or changes in service demand using appropriately governed data. Distributional impacts matter: an improved average can conceal a worse outcome for a smaller group. Synthetic agents must not be treated as substitutes for affected people’s voices.
Resilience is not one scenario. It is a family of questions.
A plan can look efficient in ordinary conditions and become fragile when several small disruptions interact. A delayed supplier may be manageable until it coincides with a demand spike and a maintenance window. Testing each disturbance independently can miss the combination that matters.
The proposed robustness program would vary the conditions around a decision, not only sample more trajectories from the same assumptions. Some tests would change numerical parameters. Others would challenge a structural assumption: a resource that was always available becomes constrained, or a response previously treated as independent becomes coordinated.
For agriculture, the question might concern water allocation under a range of seasonal conditions. For public services, it might concern capacity when demand shifts across locations. The relevant objective is not necessarily the highest expected output. It may be an acceptable service level across a range of plausible conditions, with the costs and trade-offs made explicit.
These are research directions. They require appropriate domain models, governance, and independent checks. A compelling visual of a hospital, farm, or coastal town is not evidence that the model is safe or accurate in that setting.
OPENX / POSSIBLE WORLDS
The same water. Different growing seasons.
How sensitive is the allocation to a drier season?
AI-generated concept illustration · Not a deployment photograph. Water-allocation scenarios depend on crop, soil, and weather evidence. Specialist validation is necessary before a scenario can support an operational decision.
People are not interchangeable particles.
A simulated population is a modeling choice. Its agents may differ in resources, preferences, information, and constraints, but those differences must be grounded or clearly stated as assumptions. Assigning a name or a portrait does not create a faithful representation of a real person.
For a decision about access to a service, an average response can conceal incompatible experiences. A schedule that is convenient for one group may be impossible for another. A population-level evaluation should therefore examine distributions, subgroup uncertainty, and the consequences of missing data.
We also want to distinguish disagreement in the world from uncertainty in the model. People can genuinely prefer different outcomes. That is not simply noise to be reduced. A decision tool should make the relevant trade-offs easier to discuss without implying that a simulated consensus authorizes action.
07 / Boundaries
A plausible world can still be wrong.
A simulation inherits the limits of its evidence and mechanisms. Missing variables can reverse a conclusion. Correlations can be mistaken for causes. A change in the environment can make a previously useful relationship unreliable. Long rollouts can amplify small errors into large differences.
Behavioral modeling introduces additional uncertainty. People adapt, learn, coordinate, and act for reasons absent from a dataset. Matching aggregate behavior does not demonstrate that a model can describe an individual, and making a synthetic persona more vivid does not make it more representative.
There is also a human risk: polished visuals and precise numbers can encourage overconfidence. We intend to make provenance, assumptions, and unresolved uncertainty visible alongside outputs. Such safeguards must themselves be tested; describing them here does not establish that they are effective.
SimW1 has no validated basis in this announcement for autonomous high-stakes decisions, individual eligibility judgments, or safety-critical control. Human review cannot repair an invalid model merely by approving its output. The scope of use must match the available evidence.
The most valuable output may be a boundary.
Sometimes the responsible conclusion is that the evidence does not support the requested comparison. A missing baseline, an unidentifiable causal effect, or a domain outside the evaluation scope can make a confident recommendation inappropriate. Recognizing that condition should be treated as a capability to test, not an embarrassment to hide.
Likewise, an invalid run should remain visible. If an intervention violates a resource constraint, it should not be quietly repaired in a way that changes the question. If a model fails to produce a usable output, the evaluation should count the failure rather than report only the completed runs.
Our proposed documentation approach connects these boundaries to the interface: explain what was assumed, why a comparison is limited, and what evidence or change in scope would be needed to proceed. This is the purpose of keeping a system card alongside an ambitious announcement.
08 / Documentation
The system card is part of the introduction.
Ambition should come with a record of what is known, what remains unknown, and what would have to be true before a system is relied on. The accompanying draft system card documents intended use, the status of technical disclosures, data-governance questions, risk scenarios, proposed safeguards, and release criteria.
It is not a certification or a completed safety assessment. It is a starting accountability document, with unverified items labeled explicitly rather than filled with invented technical details.
The next meaningful milestone is not a bigger claim. It is a bounded task, a reproducible baseline, an evaluation on held-out evidence, and an honest account of where the model fails. From there, the scope can grow only as the evidence supports it.
We welcome conversations about well-defined decision environments, appropriate evaluation data, and independent scrutiny. Our ambition is to help people discover what they need to learn before a choice becomes difficult to reverse.
That is the idea behind SimW1: not a future already known, but a decision made more carefully.
This research concept does not announce model availability, pricing, training specifications, or measured performance. The linked sources describe external research, not endorsements of OpenX.
 ActorsResourcesConstraintsEnvironment